
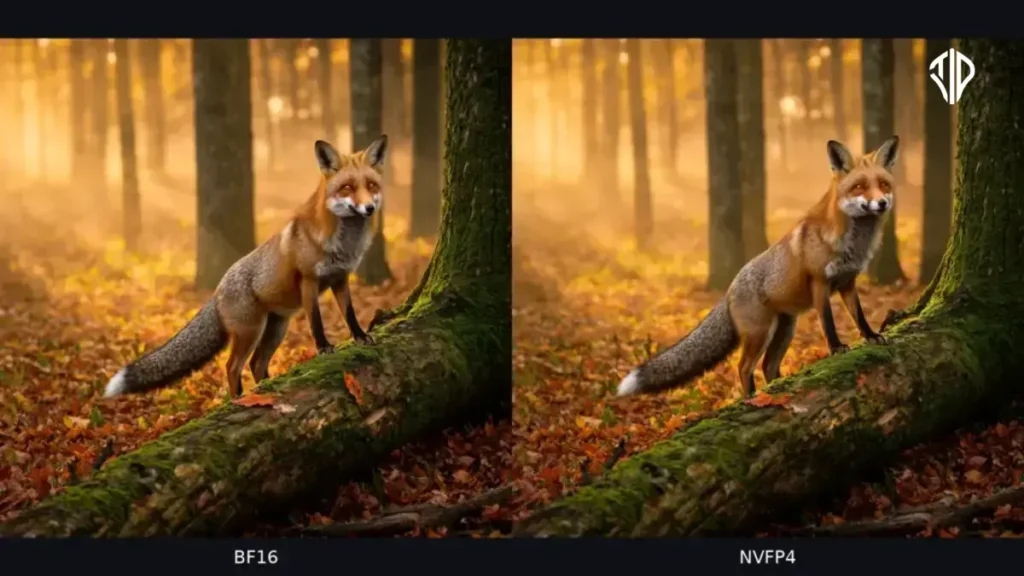
Deploying modern diffusion models in production design tools often means battling high inference latency. Generating high-resolution visuals requires running sequential passes through models with billions of parameters, creating heavy compute bottlenecks. In an official developer documentation update, new techniques reveal how hardware-software co-design can bypass these limitations for real-time visual workflows.
Black Forest Labs recently introduced FLUX 3 Image Klein, a sophisticated image editing and generation model trained on NVIDIA GB200 NVL72 systems. By pairing this model with NVIDIA Blackwell hardware and TensorRT-LLM VisualGen, developers can achieve dramatic speed improvements without sacrificing visual fidelity. The framework relies on a combination of Base and distilled model checkpoints tailored for varying latency requirements.
Understanding the FLUX 3 Image Klein Architecture
FLUX 3 Image Klein breaks away from traditional single-stream architectures by processing distinct data modalities independently before fusion. It integrates a Qwen3-VL-4B-Instruct model for precise text conditioning alongside a diffusion transformer that refines image latents. An advanced autoencoder then decodes these latents into final images or encodes reference inputs for image-to-image tasks.
The model processes text tokens, noisy target images, and optional reference inputs through separate pathways before combining them via joint attention mechanisms. This design allows the underlying hardware to optimize memory bandwidth and compute utilization across different operational phases.
Leveraging TensorRT-LLM VisualGen on Blackwell
TensorRT-LLM VisualGen is a specialized runtime built to accelerate generative visual models through low-level hardware optimizations. On NVIDIA Blackwell GPUs, the runtime unlocks features like fused kernels, multi-GPU parallelism, and advanced caching mechanisms. These features minimize the overhead typically associated with iterative sampling steps in diffusion models.
Furthermore, the runtime supports multiple precision formats, including BF16, FP8, and ultra-low-precision NVFP4. Transitioning to NVFP4 quantization on Blackwell hardware yields immediate efficiency gains, delivering up to 1.62x faster text-to-image generation compared to standard BF16 implementations.
Quantifying Performance Gains at High Resolutions
At demanding resolutions like 2048×2048 pixels, inference costs multiply exponentially due to rising attention computation overhead. However, when combining NVFP4 quantization with TensorRT-LLM optimizations, the performance leap becomes substantial. Tests on a single NVIDIA B200 GPU demonstrate up to 3.46x faster text-to-image processing for the Base model.
Image-to-image workflows see an even larger benefit, achieving up to 4.45x faster execution compared to uncompiled BF16 baseline runs. These enhancements allow creative software developers to integrate high-end generative capabilities directly into interactive design suites and automated media pipelines.
| Optimization Level | Text-to-Image Speedup | Image-to-Image Speedup | Primary Technology Lever |
|---|---|---|---|
| Uncompiled BF16 | Baseline (1x) | Baseline (1x) | Standard PyTorch Execution |
| NVFP4 Quantization | Up to 1.62x | Up to 1.58x | Lower-Precision Arithmetic |
| Combined TensorRT-LLM | Up to 3.46x | Up to 4.45x | Fused Kernels, Caching & NVFP4 |
Practical Implementation for Developers
Implementing these optimizations requires configuring specialized YAML deployment files within the TensorRT-LLM environment. Developers must map their hardware topology, select appropriate distilled or base checkpoints, and enable kernel fusion options.
By utilizing multi-GPU parallelism alongside Blackwell-specific tensor core instructions, teams can scale their rendering infrastructure efficiently. This approach transforms diffusion model deployment from a resource-heavy bottleneck into a streamlined, high-throughput production asset.
Key Takeaways
- FLUX 3 Image Klein decouples data modalities by combining a Qwen3-VL-4B-Instruct text conditioning model with a dedicated diffusion transformer.
- NVIDIA Blackwell hardware paired with TensorRT-LLM VisualGen minimizes inference latency through low-level optimizations and fused kernels.
- NVFP4 quantization provides dramatic performance leaps, achieving up to 1.62x faster text-to-image generation on standard runs.
- High-resolution testing on single B200 GPUs shows up to 3.46x text-to-image and 4.45x image-to-image speedups using combined optimizations.
Join our community by subscribing to our Weekly Newsletter to stay updated on the latest AI updates and technologies, including the tips and how-to guides.
(Also, follow us on Instagram (@tid_technology) for more updates in your feed and our WhatsApp Channel to get daily news straight to your Messaging App).
